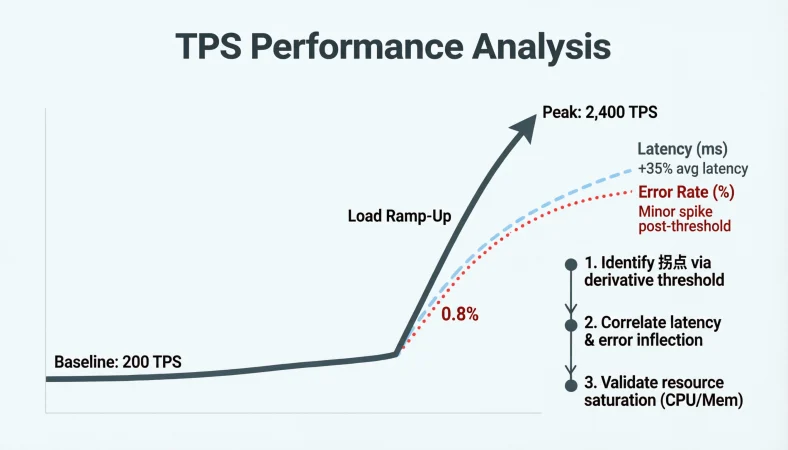
Quick Answer: A TPS response hockey stick generally refers to a hockey-stick-shaped graph showing a sharp increase in TPS (transactions per second) after a period of slower or steady growth. In performance testing, monitoring, or technical reporting, the shape can indicate a sudden traffic surge, a scaling change, or a system reaching a higher processing rate.
Top alternatives: TPS growth curve, transactions per second graph, hockey stick performance chart, TPS spike analysis, transaction throughput trend
Ever looked at a performance dashboard and seen the line suddenly shoot upward like a hockey stick? That moment can be exciting, confusing, or a tiny bit terrifying, especially when you’re responsible for explaining what happened. The phrase TPS response hockey stick can describe a sharp rise in transactions per second on a graph, often discussed in system performance, load testing, transaction processing, or capacity planning.
But a rising curve does not automatically mean everything is working perfectly. It could reflect increased demand, improved throughput, a scaling event, or even a measurement issue. Whether you’re sharing results in a work report, explaining a chart to your team, or posting a technical update, the right wording helps people understand the trend without jumping to conclusions. Let’s explore practical ways to describe, analyze, and respond to a hockey-stick-shaped TPS curve.
1. Basic TPS Response Hockey Stick Explanations
- The TPS curve shows a sharp upward trend.
Use this when describing a graph where transaction throughput rises quickly.
Meaning: The number of transactions processed per second has increased significantly. - The chart has a classic hockey-stick shape.
Use this when the graph stays relatively flat before rising steeply.
Meaning: Growth accelerates after a slower initial period. - TPS increased rapidly during the measured interval.
Use this when reporting a clear rise in transaction throughput.
Meaning: The system processed more transactions per second over that period. - The upward curve needs context before we call it a success.
Use this when reviewing a performance chart with stakeholders.
Meaning: Throughput should be assessed alongside other metrics. - Let’s confirm what triggered the sudden increase.
Use this when the graph rises unexpectedly.
Meaning: The team needs to identify the cause of the change. - The curve suggests a change in processing behavior.
Use this when the trend differs from the baseline.
Meaning: Something may have changed in demand, capacity, or measurement. - We should compare the curve with the test timeline.
Use this when interpreting load-testing results.
Meaning: Matching events to timestamps can explain the increase. - A rising TPS line is only one part of performance.
Use this when a report focuses heavily on throughput.
Meaning: Latency, errors, and resource use also matter. - The baseline helps us understand how unusual the rise is.
Use this when comparing current results with earlier runs.
Meaning: Historical data provides a useful point of reference. - Let’s verify the units and time scale first.
Use this when the chart seems unusually steep.
Meaning: Correct axes and units are essential for interpretation. - The graph shows a trend, not the cause.
Use this when someone makes assumptions based only on the curve.
Meaning: More evidence is needed to explain why TPS changed. - We need to distinguish sustained growth from a temporary spike.
Use this when the TPS peak may not last.
Meaning: Duration helps determine whether the increase is stable.
2. Professional TPS Response Hockey Stick Statements
- The TPS trend shows accelerated throughput during the observation window.
Use this in a formal performance report.
Meaning: Transaction processing increased more rapidly during the measured period. - We are validating the factors behind the observed increase.
Use this when the cause of a steep rise is still under investigation.
Meaning: The team is checking the evidence before drawing conclusions. - The result will be assessed against latency and error-rate metrics.
Use this when reporting a throughput improvement.
Meaning: Performance is being evaluated beyond TPS alone. - The observed growth will be compared with the established baseline.
Use this when preparing a benchmark summary.
Meaning: Current behavior will be measured against previous results. - We will confirm whether the increase is reproducible.
Use this when a sharp rise appears in one test run.
Meaning: Repeatability is needed before treating the result as reliable. - The chart indicates a potential change in system capacity.
Use this when throughput rises after a configuration change.
Meaning: The system may be processing more work, subject to validation. - The test conditions will be reviewed before conclusions are finalized.
Use this when the test environment may have changed.
Meaning: Differences in setup could explain the observed pattern. - We will document the timestamp and magnitude of the increase.
Use this when creating an incident or performance record.
Meaning: Specific measurements make the event easier to investigate. - The result should be interpreted within the workload profile.
Use this when comparing tests with different traffic patterns.
Meaning: Workload differences can affect throughput. - We will review resource utilization during the rise.
Use this when checking whether higher TPS strains the system.
Meaning: CPU, memory, network, and database activity provide useful context. - The team will determine whether the change reflects demand or capacity.
Use this when TPS rises during a production event.
Meaning: More traffic and improved processing ability are different explanations. - The final assessment will reflect the full performance profile.
Use this when preparing a technical conclusion.
Meaning: A balanced assessment includes throughput, reliability, and response time.
3. Funny TPS Hockey Stick Responses
- That TPS graph just unlocked turbo mode.
Use this when a dashboard suddenly shows much higher throughput.
Meaning: The increase looks dramatic and exciting. - The line went from walking to sprinting.
Use this when the graph rises sharply after a quiet period.
Meaning: The growth rate has changed noticeably. - Our graph clearly skipped leg day and chose hockey instead.
Use this in a casual team chat about the chart’s shape.
Meaning: The line resembles a hockey stick more than a gentle trend. - TPS said, “My time to shine.”
Use this when throughput reaches a new peak.
Meaning: The metric has become the star of the dashboard. - That curve took the express elevator up.
Use this when the increase happens over a short interval.
Meaning: TPS rose quickly rather than gradually. - The chart just entered its main-character era.
Use this when a dramatic curve dominates the performance report.
Meaning: The increase is the most noticeable feature. - Someone tell the graph to stop showing off.
Use this when the line rises much faster than expected.
Meaning: The change is striking, although it still needs investigation. - From flatline vibes to full send.
Use this in an informal discussion of a sudden TPS increase.
Meaning: The graph shifts from steady behavior to rapid growth. - That hockey stick came with a rocket booster.
Use this when the upward slope is unusually steep.
Meaning: The throughput increase is dramatic. - The dashboard woke up and chose upward movement.
Use this when the metric rises after a stable period.
Meaning: The trend has changed in a noticeable way. - The line is doing more climbing than my weekend plans.
Use this as a lighthearted caption for a chart.
Meaning: The graph’s upward movement is impressive. - Looks like TPS found the fast lane.
Use this when sharing a positive-looking test result with colleagues.
Meaning: Throughput appears to have increased quickly.
4. Clever Responses to a Sudden TPS Increase
- Let’s find the event that lines up with the curve.
Use this when the graph rises at a specific timestamp.
Meaning: Correlated events may help explain the increase. - Before celebrating, let’s check the latency line.
Use this when throughput rises but overall performance is uncertain.
Meaning: Higher TPS is not enough if response times worsen. - The curve is interesting; the evidence will tell the story.
Use this when the graph attracts attention during a review.
Meaning: Data should guide the explanation. - Let’s check whether the workload changed at the same time.
Use this when traffic volume might explain the rise.
Meaning: More incoming work can increase TPS without indicating better efficiency. - One steep line deserves a closer look, not an instant verdict.
Use this when a single chart is being treated as proof of success.
Meaning: The result needs context and validation. - Let’s separate the signal from the measurement noise.
Use this when the chart contains irregular spikes.
Meaning: The team needs to determine whether the trend is meaningful. - Check the scale before judging the slope.
Use this when the visual rise seems extreme.
Meaning: Axis choices can affect how dramatic the graph appears. - A repeatable result is stronger than a lucky run.
Use this when the team has one unusually strong test result.
Meaning: Consistency helps establish confidence in the finding. - Let’s compare throughput with the number of active users.
Use this when increased demand could explain the change.
Meaning: User load helps put TPS in context. - The curve gives us a question, not the final answer.
Use this when analysis is still underway.
Meaning: Further investigation is needed to establish the cause. - Let’s verify the counters before explaining the spike.
Use this when instrumentation or metric collection may be unreliable.
Meaning: Data quality must be checked first. - Follow the timeline, then follow the evidence.
Use this when several system events occurred near the increase.
Meaning: A structured investigation can narrow down possible causes.
5. Positive Responses to a Strong TPS Growth Curve
- Throughput increased significantly during the test.
Use this when a benchmark shows a verified rise in TPS.
Meaning: The system processed more transactions per second. - The upward trend is encouraging and worth validating.
Use this when the results look promising but need confirmation.
Meaning: The team can recognize progress while remaining careful. - The system handled a higher transaction rate in this run.
Use this when test conditions support a fair comparison.
Meaning: Measured throughput was higher than in the comparison run. - Let’s confirm that latency remained within our target.
Use this when reviewing a potential performance improvement.
Meaning: The throughput gain should meet response-time expectations. - The result gives us a useful benchmark for further testing.
Use this when a test produces a new performance reference.
Meaning: The result can guide future experiments. - We have a promising trend to investigate further.
Use this when the chart rises sharply but the cause is unclear.
Meaning: The team has a potentially valuable finding. - The increase appears sustained across the measured interval.
Use this when the data shows a lasting rise rather than one spike.
Meaning: The higher throughput persisted during that period. - Let’s check whether the improvement holds under repeated runs.
Use this when the result may depend on a particular test setup.
Meaning: Repeat testing can help establish reliability. - The next step is to test the system’s limits carefully.
Use this when a higher TPS result suggests room for further testing.
Meaning: Controlled testing can identify capacity boundaries. - The curve gives us a clear point for deeper analysis.
Use this when the trend identifies a notable change.
Meaning: The graph helps focus the investigation. - Let’s document the conditions that produced this result.
Use this when a test appears successful.
Meaning: Recording the setup helps reproduce the outcome. - The result is strongest when reliability improves alongside throughput.
Use this when discussing overall system performance.
Meaning: Higher TPS is more valuable when errors and latency remain acceptable.
6. Cautious Responses to a TPS Hockey Stick Curve
- We need more evidence before calling this a performance gain.
Use this when the curve rises but other metrics are unavailable.
Meaning: Throughput alone does not establish overall improvement. - Let’s rule out a measurement artifact first.
Use this when the spike seems inconsistent with other system metrics.
Meaning: Instrumentation or aggregation may have affected the result. - The increase may reflect a change in incoming demand.
Use this when traffic levels rose during the same interval.
Meaning: More requests can explain higher TPS without a capacity improvement. - We should check for retries or duplicate transactions.
Use this when a transaction counter rises unexpectedly.
Meaning: Repeated attempts may inflate the apparent throughput. - Let’s inspect errors alongside the rising curve.
Use this when the graph looks positive but the service may be failing requests.
Meaning: High TPS is less useful if error rates also increase. - The apparent gain needs a workload comparison.
Use this when comparing separate benchmark runs.
Meaning: Different workloads can produce misleading conclusions. - Let’s confirm that the time window is consistent.
Use this when charts use different sampling intervals.
Meaning: Matching time windows supports fair interpretation. - A spike does not guarantee stable capacity.
Use this when a peak appears briefly.
Meaning: Short-lived throughput may not be sustainable. - We should check whether queued work was released at once.
Use this when buffered transactions may have been processed in a burst.
Meaning: A backlog can create a temporary rise in TPS. - Let’s verify that the system remained within resource limits.
Use this when CPU, memory, or database pressure may be increasing.
Meaning: Higher throughput can come with greater resource strain. - We need to know whether the rise was expected.
Use this when a graph changes after a deployment or configuration update.
Meaning: The change should be compared with planned events. - Let’s avoid conclusions until the data is reconciled.
Use this when dashboards or logs disagree.
Meaning: Conflicting evidence should be resolved before reporting.
7. Professional Responses for TPS Performance Reports
- TPS increased from the baseline during the observation period.
Use this when summarizing a measured change.
Meaning: Throughput rose relative to the reference value. - The response curve shows a distinct acceleration phase.
Use this when the slope becomes steeper after a stable interval.
Meaning: The rate of throughput growth increased. - The increase coincided with a change in workload intensity.
Use this when test traffic changed at the same time.
Meaning: Workload conditions may explain the pattern. - The result will be assessed against predefined service objectives.
Use this when presenting findings to technical stakeholders.
Meaning: Performance will be evaluated against agreed targets. - The observed TPS peak will be checked for repeatability.
Use this when a single run produces a high result.
Meaning: The team will determine whether the peak can be reproduced. - We will review the distribution of response times.
Use this when average latency may hide slow requests.
Meaning: Percentiles can reveal performance issues that averages miss. - The report distinguishes peak throughput from sustained throughput.
Use this when a graph includes a brief high point.
Meaning: The highest rate is not necessarily the rate maintained over time. - We will correlate the TPS curve with infrastructure metrics.
Use this when investigating a performance change.
Meaning: Resource data may help explain the observed behavior. - The test environment will be documented for reproducibility.
Use this when preparing a formal benchmark report.
Meaning: Other teams should be able to understand and repeat the test. - The curve will be reviewed against the transaction mix.
Use this when different transaction types have different costs.
Meaning: The composition of the workload affects TPS. - Any instrumentation changes will be noted in the findings.
Use this when metrics collection changed during testing.
Meaning: Measurement changes may affect comparisons. - The conclusion will reflect throughput, latency, errors, and stability.
Use this when writing the final assessment.
Meaning: The report considers the broader performance picture.
8. Casual Responses for Team Chats
- Anyone know what happened at the sharp turn in this TPS graph?
Use this when sharing a chart in a team channel.
Meaning: You’re asking the team to identify the cause of the rise. - Can we line this spike up with the deployment timeline?
Use this when a recent release may be relevant.
Meaning: The team should compare timestamps for clues. - The TPS curve just got very interesting.
Use this when a new graph feature catches everyone’s attention.
Meaning: The data shows a change worth investigating. - Let’s check the logs around this point.
Use this when the increase has a clear timestamp.
Meaning: Logs may reveal events linked to the change. - Do we have latency data for the same window?
Use this when the throughput graph is shared alone.
Meaning: More metrics are needed to judge performance. - Was this expected after the scaling change?
Use this when additional resources were recently added.
Meaning: The team should verify whether the change matches expectations. - Can someone confirm the test settings?
Use this when the benchmark configuration is unclear.
Meaning: The setup needs to be verified before interpreting results. - Let’s check if this is a spike or a new steady level.
Use this when the graph rises sharply.
Meaning: The team needs to assess how long the increase lasts. - The curve looks promising, but let’s validate it.
Use this when the rise seems beneficial.
Meaning: The result should be confirmed with supporting data. - Did the request rate change at the same time?
Use this when demand could explain the increase.
Meaning: Incoming traffic may be driving throughput. - Let’s compare it with yesterday’s run.
Use this when historical results are available.
Meaning: Previous measurements may clarify whether the change is unusual. - I’ll add the timestamp to the investigation notes.
Use this when helping track a possible performance event.
Meaning: The event will be easier to reference later.
9. Responses for TPS Load Testing Results
- The load test shows a sharp rise in transaction throughput.
Use this when summarizing a hockey-stick curve in a benchmark.
Meaning: TPS increased significantly during the test. - Let’s check whether the offered load rose at the same time.
Use this when the test gradually adds more virtual users or requests.
Meaning: Increased input may explain the higher throughput. - We should identify the point where throughput began accelerating.
Use this when locating a notable change in the curve.
Meaning: The transition point may reveal useful test behavior. - Let’s compare TPS with concurrent user counts.
Use this when user concurrency varies during the run.
Meaning: Concurrency can help explain changes in throughput. - The test should continue long enough to assess stability.
Use this when the peak is brief.
Meaning: A longer observation may reveal whether performance is sustained. - Let’s review the ramp-up schedule.
Use this when traffic was introduced gradually.
Meaning: The load profile may explain the curve’s shape. - We need to verify that the generator was not the bottleneck.
Use this when the load-testing client may have limited throughput.
Meaning: Test infrastructure can constrain the measured result. - Let’s review server-side saturation indicators.
Use this when the system approaches high load.
Meaning: Resource limits may explain changes in TPS. - We should compare error rates before and after the rise.
Use this when throughput improves but reliability is uncertain.
Meaning: The test should reveal whether failures increased. - Let’s repeat the test with the same workload profile.
Use this when confirming a surprising result.
Meaning: Repeated runs help establish whether the pattern is reliable. - The peak rate and sustainable rate should be reported separately.
Use this when the test has a short maximum burst.
Meaning: The highest observed TPS may not be maintainable. - We’ll document the test configuration with the final graph.
Use this when preparing results for a review.
Meaning: Context helps others reproduce and interpret the test.
10. Responses to TPS Spikes and Anomalies
- The spike needs to be checked against the raw measurements.
Use this when a dashboard shows an unusual jump.
Meaning: The aggregated graph should be verified against underlying data. - Let’s inspect the timestamps for missing or delayed samples.
Use this when the graph has gaps or sudden jumps.
Meaning: Collection issues may distort the apparent trend. - Could a batch process explain the temporary increase?
Use this when background work may have completed in a burst.
Meaning: A scheduled process could account for the change. - Let’s check whether retries increased during this interval.
Use this when request failures may trigger repeated attempts.
Meaning: Retries can change measured transaction volume. - We should confirm whether the metric counts attempts or successful transactions.
Use this when the TPS definition is unclear.
Meaning: Different counting methods can produce different interpretations. - The spike may be real, but we need corroborating metrics.
Use this when the graph appears unusual yet plausible.
Meaning: Independent measurements can support or challenge the finding. - Let’s compare application logs with infrastructure events.
Use this when investigating an unexplained increase.
Meaning: Multiple data sources may reveal the cause. - Check whether the aggregation interval changed.
Use this when the chart looks different after a monitoring update.
Meaning: Different sampling can affect the displayed pattern. - Let’s verify that duplicate events are not being counted.
Use this when the counter rises more than expected.
Meaning: Duplicate records could inflate the metric. - We should classify the event before assigning severity.
Use this when a TPS anomaly may or may not indicate an incident.
Meaning: Severity should depend on verified impact. - Let’s track whether the spike repeats.
Use this when the same pattern might occur periodically.
Meaning: Recurrence can help identify the underlying mechanism. - We’ll record the anomaly and its confirmed explanation.
Use this when the investigation is complete.
Meaning: Documentation supports future troubleshooting.
11. Responses About TPS Scaling and Capacity
- Let’s check whether scaling coincided with the TPS increase.
Use this when new instances or resources were added.
Meaning: Scaling may have contributed to higher throughput. - The curve may show the effect of added processing capacity.
Use this when throughput rises after a capacity change.
Meaning: Additional resources may allow more transactions to be processed. - We need to confirm that the extra capacity is being used.
Use this when more resources have been provisioned.
Meaning: Resource allocation does not guarantee effective utilization. - Let’s compare throughput per instance.
Use this when the number of running instances changed.
Meaning: Per-instance metrics help distinguish scaling effects from overall growth. - Check whether database throughput is keeping pace.
Use this when the application tier scales but the database may not.
Meaning: A downstream bottleneck can limit overall TPS. - Let’s monitor queue depth during the rise.
Use this when requests may be waiting for processing.
Meaning: Growing queues can signal that demand exceeds processing capacity. - We should check connection pools and worker limits.
Use this when the system appears unable to use available resources.
Meaning: Configuration limits can constrain throughput. - The next test should explore the capacity boundary safely.
Use this when the system shows a promising increase.
Meaning: Controlled testing can identify the sustainable operating range. - Let’s compare resource costs with the throughput gain.
Use this when scaling increases infrastructure use.
Meaning: Performance improvements should be assessed alongside cost. - A higher TPS peak does not automatically prove better scalability.
Use this when a single result is being used to claim scalability.
Meaning: Scalability requires evidence across relevant workload levels. - We’ll test the response under sustained demand.
Use this when checking whether added capacity remains effective.
Meaning: Long-running tests reveal stability under load. - Let’s document the configuration that delivered the result.
Use this when a scaling experiment succeeds.
Meaning: Recorded settings help reproduce the outcome.
12. Responses About TPS, Latency, and Errors
- TPS increased, but how did response time change?
Use this when a report includes throughput but omits latency.
Meaning: Higher transaction rates should be considered alongside responsiveness. - Let’s review the 95th and 99th percentile latency.
Use this when averages might hide slow requests.
Meaning: Tail latency reveals the experience of slower transactions. - We need to check whether the error rate rose with TPS.
Use this when the curve climbs quickly.
Meaning: More transactions may not mean more successful outcomes. - Let’s compare successful TPS with total attempts.
Use this when retries or failures may inflate the total count.
Meaning: Successful throughput gives a clearer view of useful work. - The system should meet its latency target at the measured rate.
Use this when evaluating performance against a service objective.
Meaning: Throughput must align with expected response times. - A throughput gain is less useful if timeouts also increase.
Use this when higher TPS accompanies service degradation.
Meaning: Reliability is essential to judging the result. - Let’s look for queueing delays near the curve’s turning point.
Use this when response times change as load increases.
Meaning: Queues may help explain the shift in performance. - We should compare latency distributions across test runs.
Use this when deciding whether a change improved performance.
Meaning: Distribution comparisons reveal more than a single average. - Let’s confirm the error codes before interpreting the result.
Use this when failures occur during the TPS increase.
Meaning: Error categories help identify the source of problems. - The best result balances throughput, speed, and reliability.
Use this when summarizing system performance.
Meaning: A complete assessment considers multiple measures. - Let’s check whether latency increased after saturation.
Use this when TPS stops growing while response times rise.
Meaning: The system may be approaching a bottleneck. - We’ll report the full metric set rather than TPS alone.
Use this when presenting results to management or engineering teams.
Meaning: Context makes the performance conclusion more trustworthy.
13. Creative Ways to Describe a TPS Hockey Stick Chart
- A steady baseline followed by a steep upward climb.
Use this in a chart caption or report summary.
Meaning: The graph transitions from relatively stable throughput to rapid growth. - A clear acceleration in transaction throughput.
Use this when the slope becomes noticeably steeper.
Meaning: TPS is increasing at a faster rate. - A sharp transition from gradual growth to rapid expansion.
Use this when the curve has a distinct turning point.
Meaning: The rate of increase changes substantially. - A pronounced rise in TPS during the final test phase.
Use this when the increase occurs near the end of a run.
Meaning: The largest growth appears in the final interval. - A hockey-stick pattern that warrants further validation.
Use this when the shape is striking but unexplained.
Meaning: The visual pattern needs supporting evidence. - A sustained upward trend following a stable period.
Use this when the higher level persists.
Meaning: Throughput remains elevated after the initial change. - A sudden throughput jump aligned with a system event.
Use this when the timestamps appear to match a deployment or scaling change.
Meaning: A related event may explain the rise. - A steep curve with performance implications still to be confirmed.
Use this when latency and errors are not yet analyzed.
Meaning: The chart alone cannot establish whether the result is beneficial. - A visible increase in transaction-processing activity.
Use this when describing the chart to a nontechnical audience.
Meaning: The system is handling more transaction activity. - A sharp rise that differs from the established baseline.
Use this when the current run is unlike earlier tests.
Meaning: The result represents a notable change from previous behavior. - A throughput trend with a distinct inflection point.
Use this in a formal technical report.
Meaning: The curve changes direction or slope at a particular point. - A graph that raises useful questions about capacity and demand.
Use this when the chart is being used to guide investigation.
Meaning: The trend can direct further analysis.
14. Confident Responses for Technical Presentations
- The graph shows a clear increase, and we are validating the cause.
Use this when presenting early findings.
Meaning: The observed trend is clear, but its explanation is still being checked. - We will judge the result against our agreed performance targets.
Use this when explaining the evaluation criteria.
Meaning: The result will be measured against defined objectives. - The next step is to establish whether the increase is sustainable.
Use this when discussing a high TPS peak.
Meaning: The team needs to assess whether the rate can be maintained. - We have identified the key interval for further investigation.
Use this when the curve has a clear turning point.
Meaning: The analysis has a specific period to examine. - The conclusion will include both throughput and service quality.
Use this when stakeholders focus only on TPS.
Meaning: Performance quality is broader than transaction volume. - We are separating confirmed findings from possible explanations.
Use this when the cause is not fully established.
Meaning: The report will distinguish evidence from hypotheses. - The baseline comparison will show how significant the change is.
Use this when explaining why historical data matters.
Meaning: The earlier result provides context for the new measurement. - We will repeat the test under consistent conditions.
Use this when a result needs confirmation.
Meaning: A controlled rerun can establish repeatability. - The resource metrics will help explain the throughput pattern.
Use this when investigating system behavior.
Meaning: Infrastructure data may reveal what drove the increase. - We will communicate the limitations alongside the result.
Use this when presenting a benchmark to decision-makers.
Meaning: The audience will understand what the data can and cannot prove. - The evidence will determine whether this is an improvement.
Use this when a graph looks promising but other metrics are pending.
Meaning: The final judgment will be based on measured results. - We have a clear path for validating the finding.
Use this when closing a technical presentation.
Meaning: The team knows which checks come next.
15. Smart and Preventive Responses to TPS Hockey Stick Trends
- Define the TPS metric before building the dashboard.
Use this when setting up performance monitoring.
Meaning: Everyone should understand what is being counted. - Set alerts for unusual changes in throughput.
Use this when monitoring production systems.
Meaning: Alerts can help teams investigate unexpected behavior promptly. - Track TPS alongside latency and error rates.
Use this when designing a performance dashboard.
Meaning: Multiple metrics provide a more complete view. - Keep a record of deployments and configuration changes.
Use this when investigating sudden graph changes.
Meaning: Event history can help explain changes in system behavior. - Use consistent sampling intervals for comparisons.
Use this when preparing benchmark charts.
Meaning: Matching measurement windows makes comparisons more reliable. - Repeat unusual results before treating them as a baseline.
Use this when a single run produces a dramatic curve.
Meaning: Repeated evidence reduces the risk of drawing conclusions from an anomaly. - Document the workload profile for each test.
Use this when comparing TPS across runs.
Meaning: The workload is necessary context for interpreting throughput. - Monitor queue depth and resource saturation.
Use this when checking whether the system can handle higher load.
Meaning: These metrics can expose bottlenecks behind the curve. - Separate peak throughput from sustainable throughput in reports.
Use this when publishing performance results.
Meaning: Short bursts should not be mistaken for long-term capacity. - Investigate spikes before changing production capacity.
Use this when an unexpected rise triggers a scaling discussion.
Meaning: The cause should be understood before making costly changes. - Keep the raw data available for deeper analysis.
Use this when a summary chart hides important detail.
Meaning: Raw measurements support verification and troubleshooting. - Turn every unusual curve into a documented learning opportunity.
Use this after investigating a surprising performance trend.
Meaning: Recording the findings can improve future monitoring and testing.
FAQs
What does TPS response hockey stick mean?
It usually describes a graph where transactions per second rise sharply after a flatter period.
Does a hockey-stick TPS curve always mean better performance?
No. Check latency, errors, workload, and resource use before calling it an improvement.
What can cause a sudden TPS increase?
Possible causes include higher demand, scaling changes, batch processing, retries, or measurement issues.
How should I explain a TPS hockey-stick chart professionally?
Describe the increase, compare it with the baseline, and state what evidence is still needed.
Is a rising TPS curve suitable for a technical report?
Yes. Include the time window, test conditions, baseline, and supporting performance metrics.
What should I check when TPS rises suddenly?
Review logs, workload changes, deployments, retries, metric collection, latency, and error rates.
Can humor be used when discussing a TPS spike?
Yes, in casual team chats, but keep formal incident reports clear and factual.
What is the difference between TPS and response time?
TPS measures transactions processed per second; response time measures how long a request takes.
How do I know whether high TPS is sustainable?
Run a controlled sustained-load test and monitor latency, errors, queues, and resource utilization.
How can I make a TPS graph easier to understand?
Label the axes, mark important events, show a baseline, and include a clear time range.
Conclusion
A TPS response hockey stick can be an exciting sight on a dashboard, but the real story lies behind the curve. A sharp rise may reflect increased demand, added capacity, a change in workload, or an issue with measurement. The smartest response is to describe the trend clearly, compare it with a baseline, and check latency, errors, resource usage, and test conditions before drawing conclusions.
Whether you’re writing a performance report, sharing a chart with colleagues, or investigating a sudden change, precise language makes your findings easier to trust. Save these examples for your next review, share them with your team, and keep turning confusing curves into useful insights.